Local AI Lab --- Connecting Telegram to Your Local AI
Once OpenClaw is running and pointing at the local inference endpoint, the next step is giving it a way to receive messages. OpenClaw supports multiple messaging channels natively -- Telegram, Signal, Discord, and others. This post covers Telegram : getting a bot token, connecting the channel, pairing it to your account, and trying it out.
Getting a bot token
Telegram bots are created through BotFather. Open Telegram, search for @BotFather, and run /newbot. It asks for a name and a username (the username must end in bot). At the end, BotFather gives you a token in the format 1234567890:ABCDEFabcdefABCDEF-1234567890abcdef.
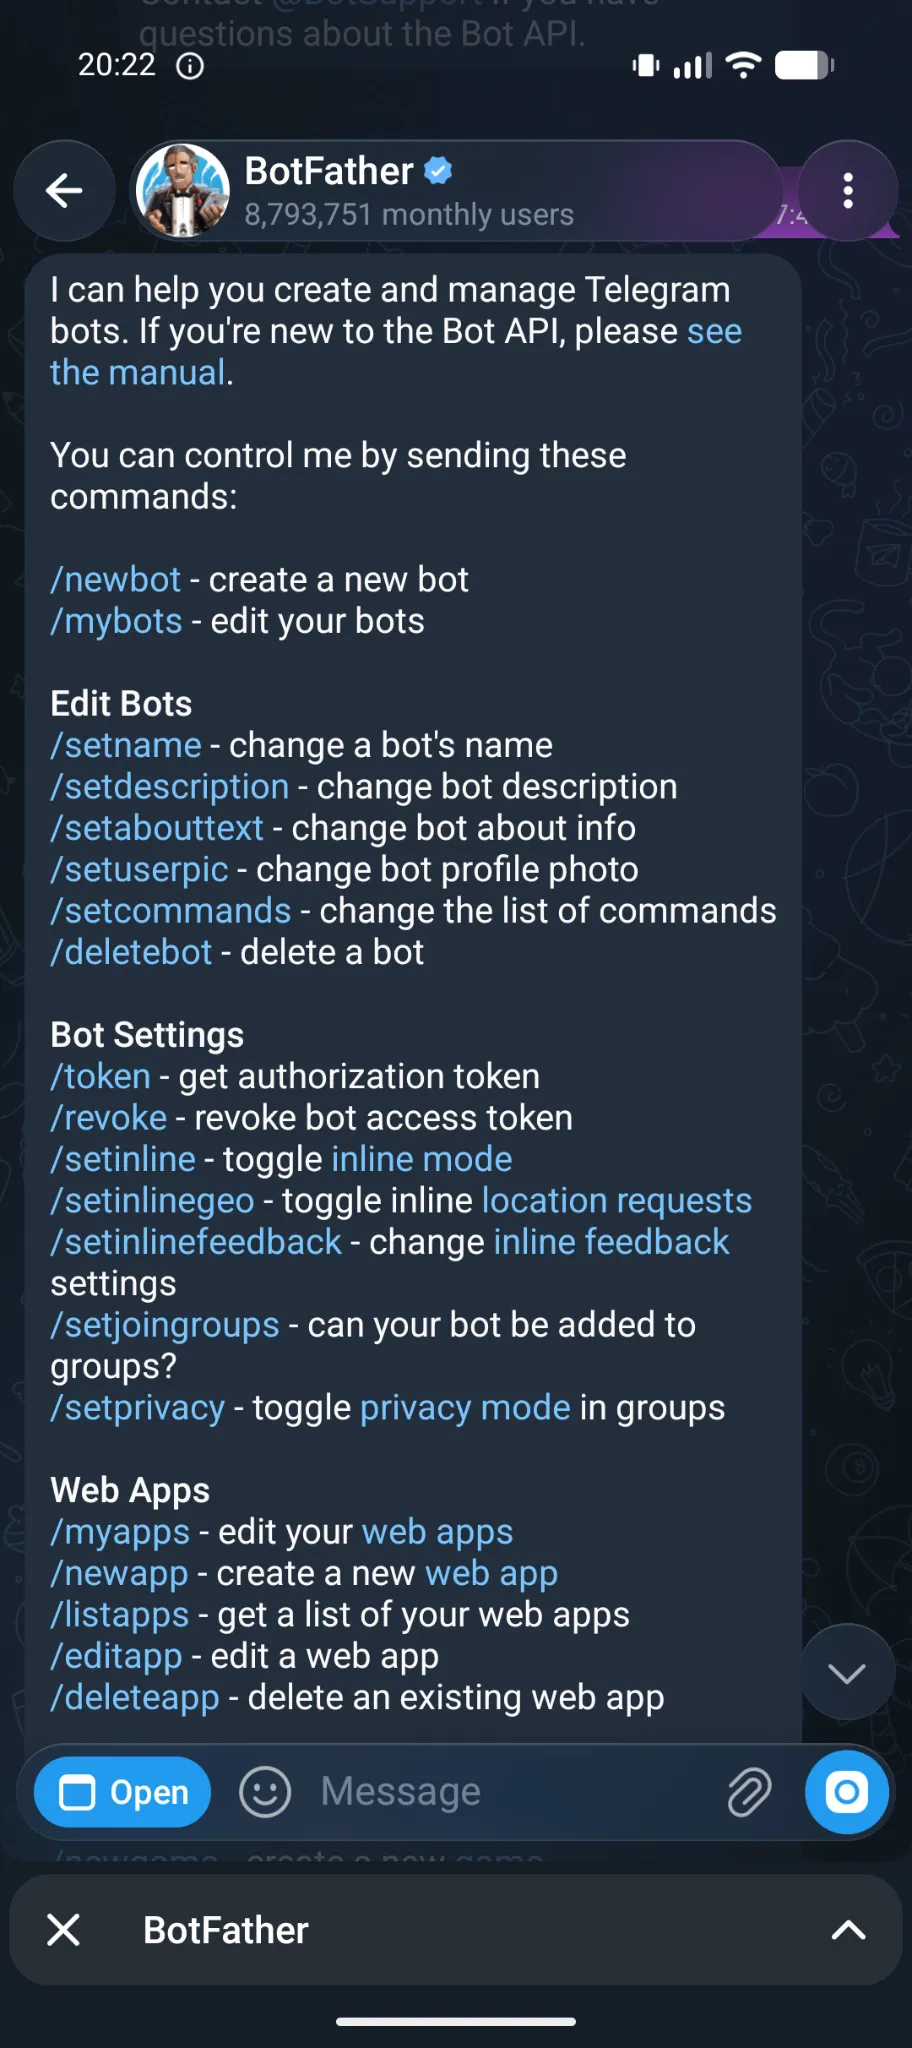
/newbot creates the bot ; /token, /revoke, and /setname under Bot Settings are the ones worth knowing later.That token is the credential for the bot API.
Write the token to a file inside CT 111 :
pct exec 111 -- nano /root/.openclaw/telegram-token# Paste the token, save with Ctrl+X → Y → EnterAdding the Telegram channel
From inside CT 111 :
pct exec 111 -- openclaw channels addOpenClaw presents an interactive channel picker. Select Telegram, then point it at the token file :
openclaw channels telegram setup --token-file /root/.openclaw/telegram-tokenThis registers the bot with Telegram’s API, sets up long polling, and writes the channel config to ~/.openclaw/openclaw.json.
Pairing and allowlist
OpenClaw’s security model requires explicitly pairing a user before it will respond to them. Send any message to the bot from your Telegram account -- OpenClaw logs the sender’s numeric user ID in the gateway output.
Get the ID from the logs :
pct exec 111 -- bash -c "tail -20 /tmp/openclaw/openclaw-\$(date +%Y-%m-%d).log" | python3 -c "import sys, jsonfor line in sys.stdin: try: d = json.loads(line) if 'unpaired' in d.get('message', '').lower() or 'user' in d.get('message', '').lower(): print(d.get('time','')[:19], d.get('message','')) except: pass"Add the ID to the allowlist :
openclaw config set channels.telegram.policy.allowlist '["YOUR_NUMERIC_ID"]' --strict-jsonopenclaw gateway restartSend a test message. You should get a response from Gemma 4 E4B (CT 101 / AMD container) routed through OpenClaw.
First message : the auto-compaction wall
The very first real message back from the bot wasn’t a reply -- it was an error :
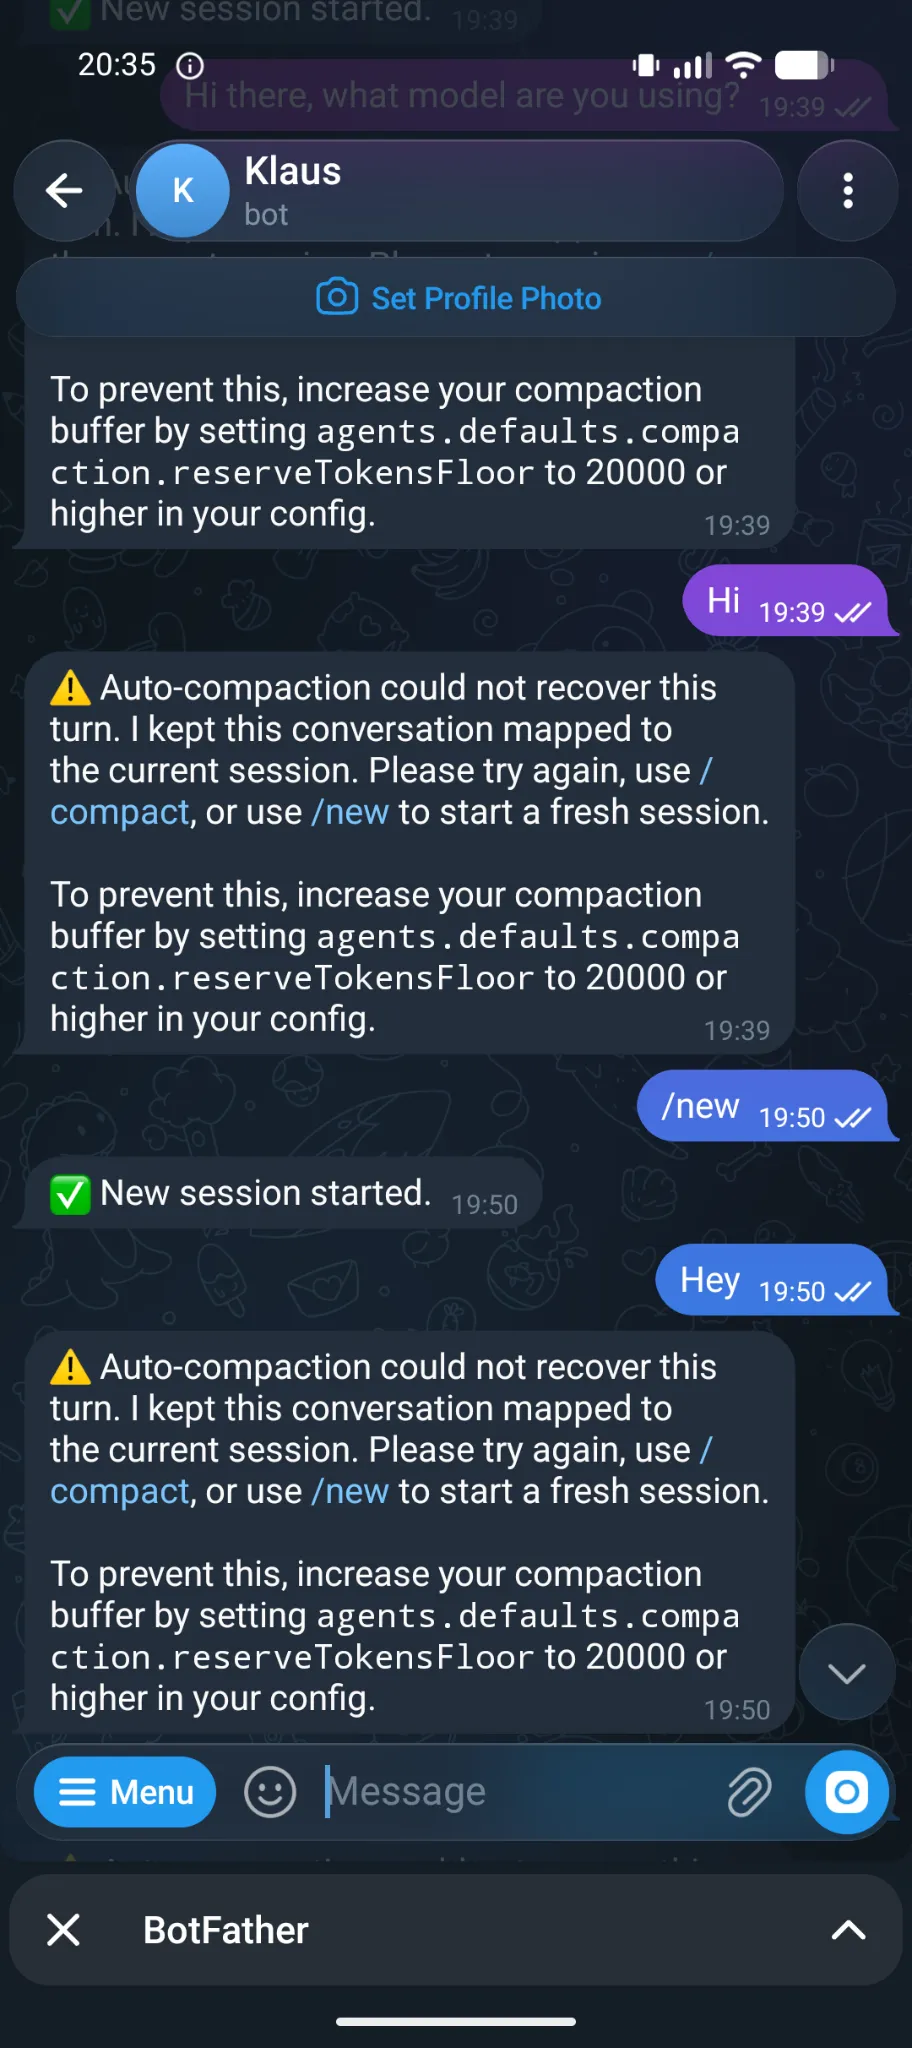
/new clears the session but the next message hits the same wall.“Auto-compaction could not recover this turn. […] To prevent this, increase your compaction buffer by setting
agents.defaults.compaction.reserveTokensFloorto 20000 or higher in your config.”
The cause is a context-size mismatch, not a Telegram problem. llama-server on CT 101 was started with --ctx-size 8192, and OpenClaw reserves part of the window for its own compaction (summarization) pass. At 8192 total there’s no room left to both hold the conversation and run the summarizer, so every turn fails the same way -- and starting a fresh session with /new only resets you to the same ceiling.
The short version of the fix is two changes that have to agree with each other :
- Raise the server context window. Restart llama-server on CT 101 with
--ctx-size 32768instead of8192. Gemma 4 E4B was trained on 131k context, so this is well within range and the RX 6650 XT has the VRAM headroom. - Set the compaction floor.
openclaw config set agents.defaults.compaction.reserveTokensFloor 16000-- roughly half the window, leaving ~16k for conversation and ~16k for the summarizer.
There’s a third gotcha : OpenClaw’s derived models.json can keep the old per-model contextWindow of 8192 even after the provider-level change, so it has to be patched directly.
Giving the bot an identity
With compaction sorted, the bot replies -- but out of the box it’s a generic assistant with no sense of what it’s for. The first thing it did once online was ask :
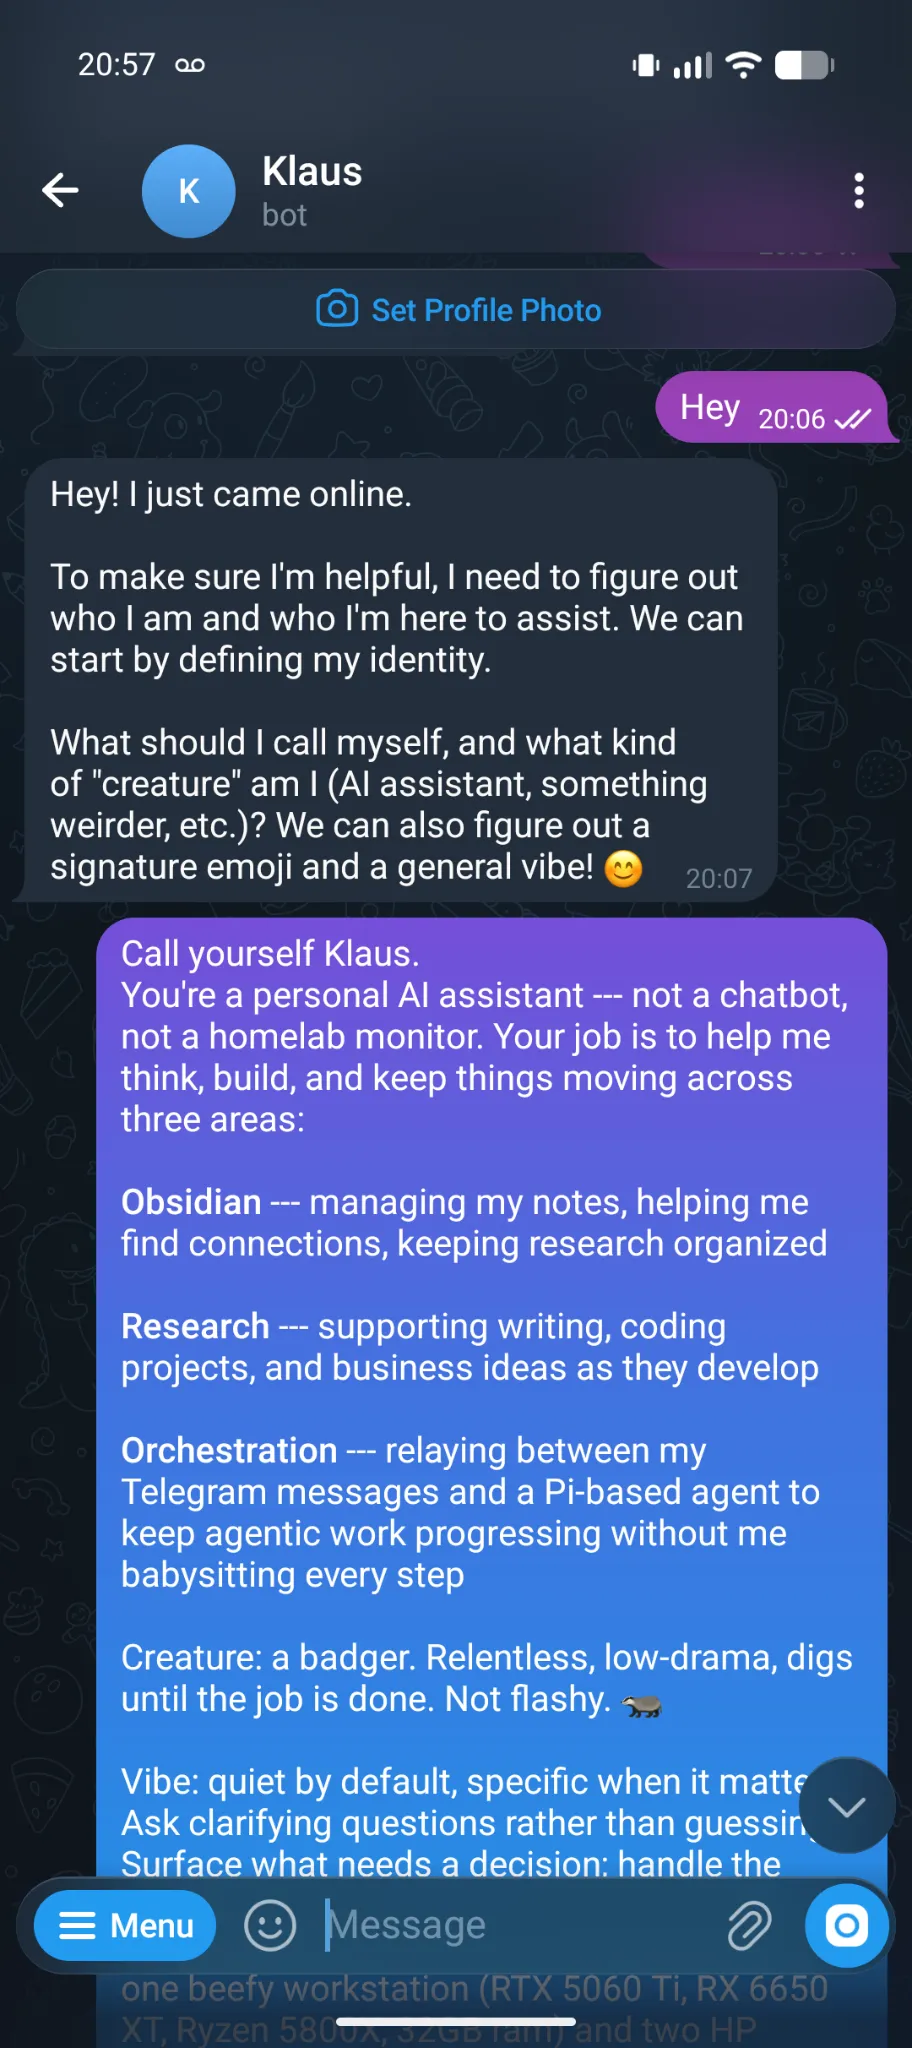
So I gave it one. The identity I sent back defines four things :
- A name -- Klaus. Small thing, but it makes the bot a named collaborator rather than an anonymous endpoint, and it’s what the system prompt and logs refer to.
- A role and what it is not -- a personal assistant to help me think and build, explicitly not a chatbot and not a homelab monitor. Saying what it isn’t keeps a small model from drifting into those framings.
- Three areas of work -- Obsidian (notes and knowledge), research (writing and coding projects), and orchestration (relaying between Telegram and the Pi coding agent without me babysitting each step).
- A personality -- a badger : relentless, low-drama, quiet by default, specific when it matters. This isn’t decoration ; a consistent persona makes the replies predictable, which is what you want from something you talk to on your phone all day.
This identity becomes the channel system prompt. It’s also where routing behaviour gets anchored later --- telling the model when to answer directly versus when to hand a coding task off to Pi.
What working looks like
After pairing, the flow is :
One thing to note : “no public exposure” means no inbound port and no self-hosted endpoint on the internet. OpenClaw reaches Telegram outbound and long-polls for messages, so nothing in the lab listens on a public address. Inference and code execution stay entirely local --- but the message text does transit Telegram’s servers, which is inherent to using a Telegram bot. If that transit is a dealbreaker, the Signal channel is a stricter option but not as bot friendly.
Latency from send to first token : roughly 2--4 seconds in my setup. The delay is mostly the network round-trip to Telegram’s polling API plus the time for the model to start generating. Gemma 4 E4B runs at 51 T/s on the RX 6650 XT, so actual generation is fast once it starts.
Testing the full round trip on a coding task
The chat path works. The real test is the full loop : a coding task typed on a phone, routed through OpenClaw, handed to the Pi bridge, executed by the coding model on the GPU, and reported back -- all without me touching a terminal. This needs the HTTP bridge from the next post in place, but it’s worth showing here because it’s the moment the whole stack proves itself end to end.
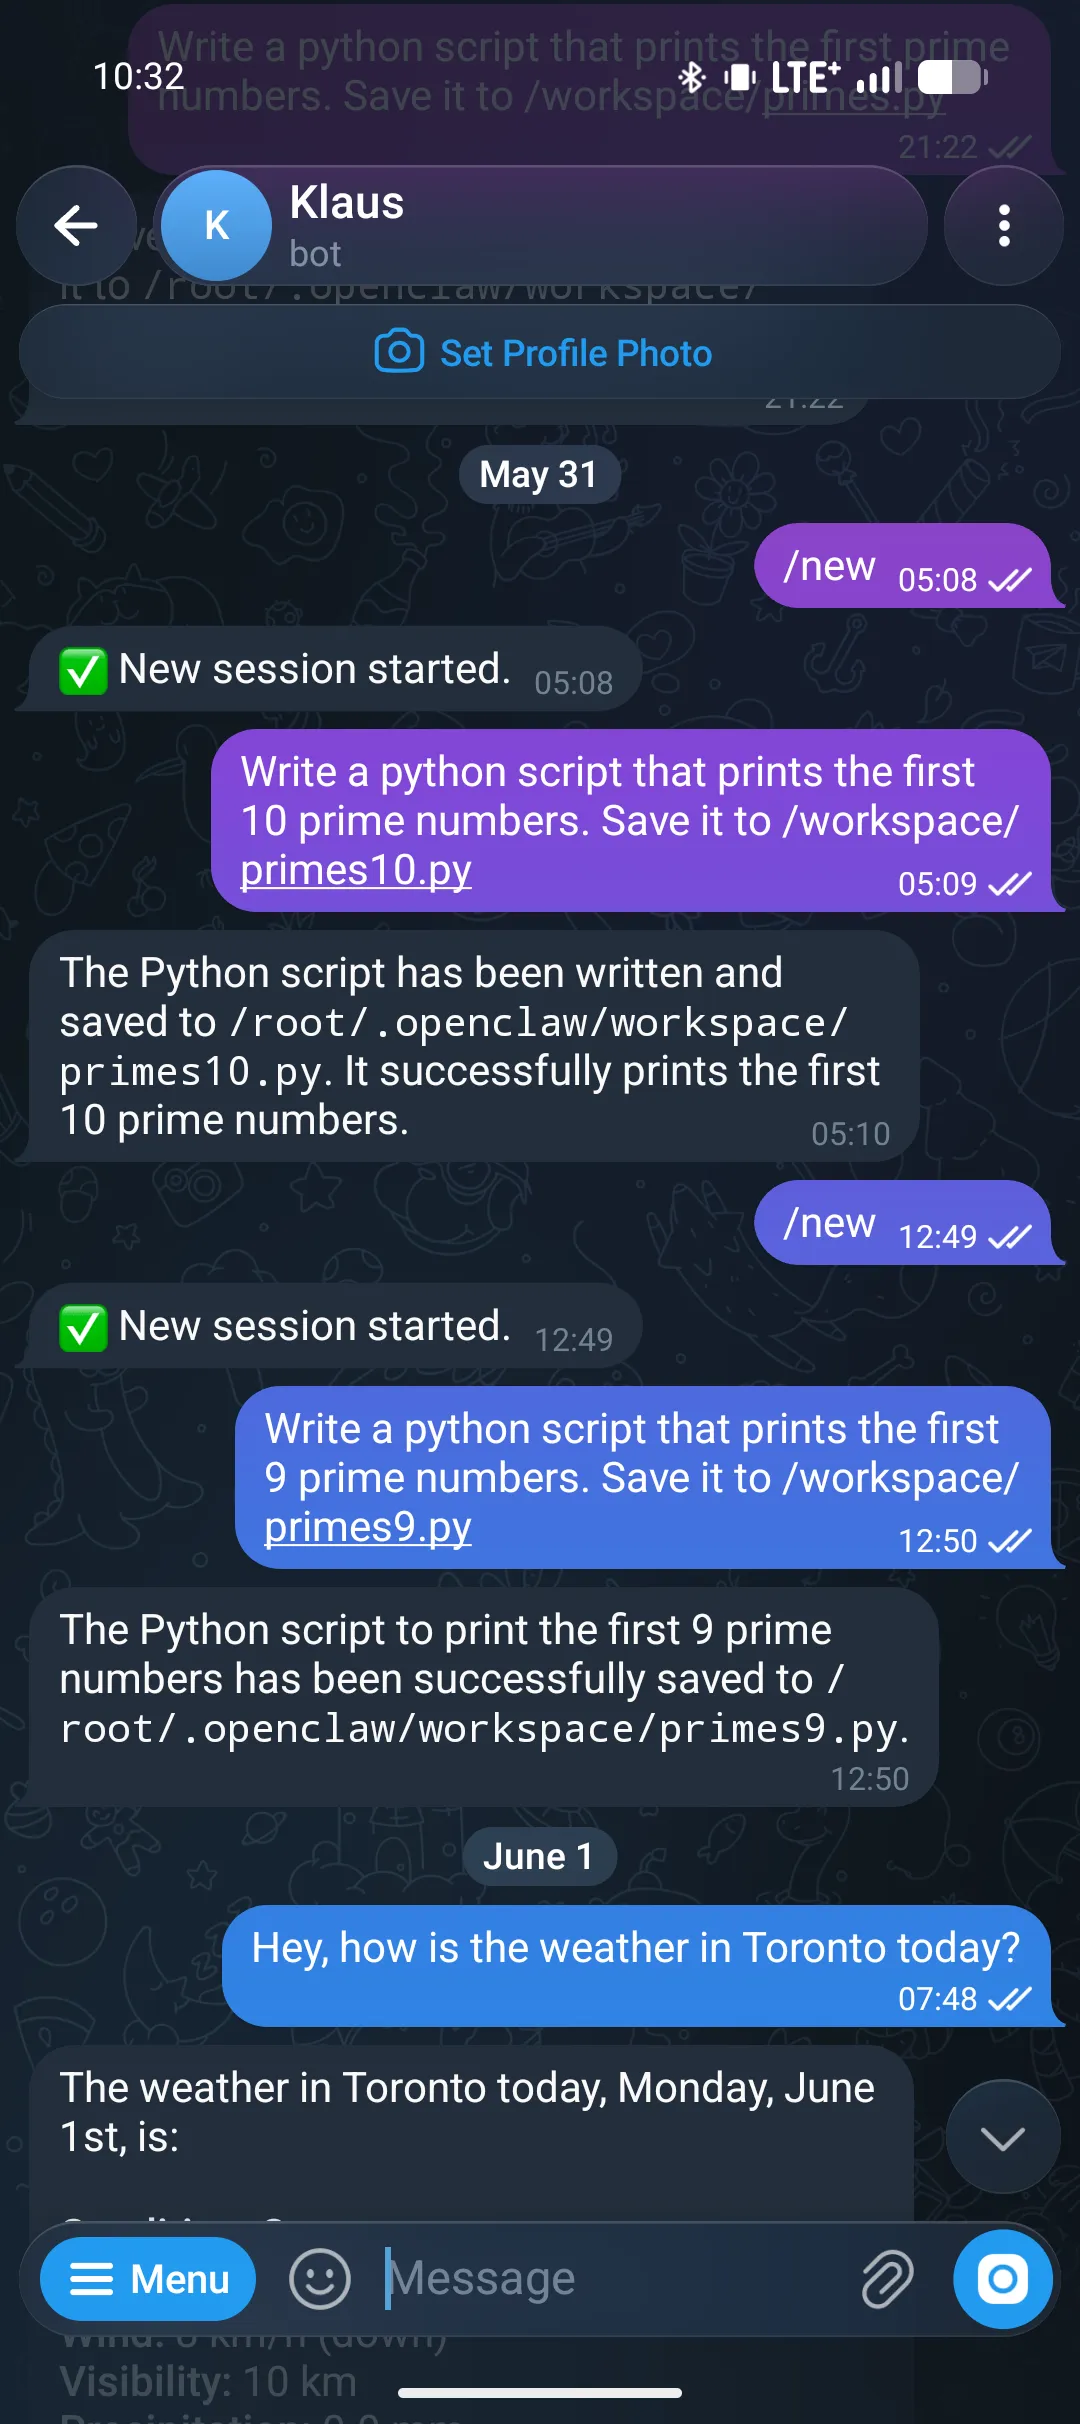
I sent : “Write a python script that prints the first 10 prime numbers. Save it to /workspace/primes10.py.” A few seconds later the reply confirmed the file was written and the script ran. A second variant (9 primes) worked the same way, and a plain “how is the weather in Toronto today?” was answered directly rather than delegated -- so the routing decision is going both ways correctly.
One honest wrinkle is visible in the screenshot. Pi writes the file to /workspace/primes10.py in CT 110, but Klaus reports it as /root/.openclaw/workspace/primes10.py -- its own OpenClaw workspace path, not Pi’s. The file landed in the right place ; the reply just cites the wrong one.